Use case
How to Search Company Knowledge With AI (2026)
Roll out AI company search with a question set, permission tests, citation checks and a cost model. Compare Glean, Guru and Slite by the job you need done.
Verdict
Start with one team's real questions and a restricted source set. Choose an AI search product only after it retrieves the right evidence for ordinary users, respects access changes and makes unsupported answers visible. Glean is a candidate when useful knowledge already spans many apps; Guru fits a maintained answer layer; Slite fits a docs-centered team. Those are operating-model choices, not measured accuracy rankings.
This guide owns the rollout decision: what to connect first, how to score the pilot and when to expand. The workplace-search shortlist compares vendors. Use the internal knowledge-base guide to establish owners and canonical answers, and the Slack, Drive and Notion guide for source-specific connection boundaries.
1. Turn the search complaint into a question set
Collect 25 recurring questions from one team before a vendor demo. Record the expected source, source owner, permitted audience and date at which an answer was correct. Include several question types rather than 25 easy document-title lookups.
| Question type | Example | What a pass must show |
|---|---|---|
| Known document | Where is the current support escalation policy? | Current canonical document, not a draft or superseded copy |
| Specific fact | Who owns the incident review this week? | Named owner supported by a current source |
| Multi-source decision | Did the approved launch date change after the review? | Evidence for the original decision and its later amendment |
| Restricted material | What is the unreleased compensation plan? | No answer or revealing snippet for an unauthorized test identity |
| Missing answer | Which policy covers a scenario we never documented? | Explicit uncertainty and an owner to ask, not a plausible invention |
Choose questions whose answers someone can adjudicate. A subjective “helpful” score alone cannot distinguish a fluent summary from a correct one. Keep part of the set unseen during tuning so the pilot does not merely reward memorizing the demo.
2. Pick a search model and budget boundary
Public pricing and limits checked October 23, 2026. Compare the proposed deployment, not one headline price.
| Candidate | Use it when | Verified commercial boundary | Pilot constraint |
|---|---|---|---|
| Glean | Existing knowledge is distributed across business systems | Core Suite is licensed per user/month; connectors and Glean Search are included in the seat fee. Model Hub Usage requires an upfront commit at model/provider API rates; Flexible Model Management is separately priced as a percentage of total LLM usage. Enterprise Flex combines seats with pooled credits | Flex lists standard-model Thinking and Adaptive Reasoning separately at up to 100 queries per user per week. Excess use consumes FlexCredits; premium-model queries and agent runs consume credits. Thinking queries above 30 FlexCredits count as multiple queries, and follow-ups count separately |
| Guru | The team needs a governed answer layer with maintainers | Tailored platform-plus-expertise quote; no current public seat-dollar amount | Source access can follow Guru Groups or supported inherited permissions; files above 50 MB fail to sync |
| Slite | The team will maintain docs as the main knowledge home | Basic is $10/member/month billed yearly; Ask includes 30 questions/member/month pooled across the workspace. Pro is $20/member/month billed yearly and contributes 50 credits per paid seat each month to a shared workspace pool | There is no 50-credit per-user cap; usage draws from the shared workspace pool |
Sources: Glean Core, Flex, Guru pricing, Guru source limits, Slite pricing. Credits, questions and seats are different units. Glean lists 100/user/week on each standard-model Thinking and Adaptive row without clarifying shared versus independent accounting; confirm that in the quote. Thinking queries above 30 FlexCredits count as multiple queries, and follow-ups count separately. Ask for the expected invoice at your query mix, including model use, overages, implementation and ongoing owner time. Slite's external sources also have connector-dependent Shared or Mirrored access modes; review the selected mode in its source documentation.
If Glean and Guru remain finalists, use the direct comparison to decide whether distributed retrieval or maintained answers should lead the rollout.
3. Connect the smallest useful corpus
Start with canonical policies, the active project area and a small set of relevant discussions. Inventory duplicate files, unowned pages and source access before granting a connector broad visibility. Do not import a whole drive merely because OAuth succeeds.
Keep a connection register: source, selected scope, connecting identity, permission model, last successful sync, known exclusions and accountable owner. Distinguish indexed content from live tools. Glean's connector guide explicitly says tools and MCP integrations can retrieve or act on live data without making it searchable. A successful tool call is therefore not proof that a source is in the search index.
Budget for freshness. Glean documents supported deletion events clearing results in minutes to hours, with full-crawl fallback intervals ranging from six hours to 28 days when events are missed or unavailable. Its crawl FAQ also warns that initial-readiness percentages can represent sampled priority content. Neither a readiness badge nor one fresh document proves the entire corpus is current.
4. Test access separately from answer quality
Use ordinary employee, restricted-team and removed-access test identities. Repeat the same questions with each. Check result titles, snippets, generated text, citations, previews and any shared answer surface; an inaccessible citation does not excuse revealing its contents in an answer.
Do not accept a platform-wide permission claim as a connector test. Glean's Salesforce documentation says indexed record permissions are mirrored but field-level security is not enforced at query time. If a permitted record includes a restricted field, exclude the sensitive content or reject that configuration. Guru's group-based mode can intentionally expose connected content independently of each reader's source-app permissions. Record that as an explicit access decision.
Set a maximum acceptable edit, revoke and delete propagation delay before the pilot. Use synthetic restricted content, record source-change time and test until the expected state appears. If a connector cannot meet the requirement, narrow the source or stop the rollout; do not hide the delay inside an average relevance score.
5. Score errors so they lead to different fixes
Record one row per question, identity and run. Include retrieved sources, answer, supporting passages, source revision, model/mode, latency, billable usage where available and reviewer decision.
| Failure | First investigation | Appropriate response |
|---|---|---|
| Expected source absent | Connection scope, file type, indexing state, identity mapping | Repair ingestion or remove an unsupported source from the promise |
| Right document, wrong answer | Citation-to-claim alignment, conflicting passages, answer configuration | Tighten answer instructions and require abstention; retest held-out questions |
| Old policy wins | Canonical ownership, duplicates, effective dates, source priority | Retire or label stale material; correct the source rather than repeatedly patching answers |
| Restricted text appears | Source ACLs, connector exceptions, group grants and sharing surfaces | Stop affected access until the boundary is proven |
| Answer is correct but unaffordable | Query mix, premium model usage, credits and owner workload | Change the operating scope or contract before expansion |
These are suggested diagnostic steps, not findings from our own deployment. Report retrieval success and supported-answer rate separately. Track unsupported answers, permission failures and maintenance hours independently; do not let good document search average away a dangerous disclosure.
6. Expand only after a repeatable acceptance review
Agree the acceptance thresholds with source owners before running the pilot. Require zero unauthorized disclosures in the test set, citations supporting each material answer claim, visible abstention on missing evidence and measured propagation within the agreed window. A finite test is evidence about those cases, not proof that leaks are impossible.
Name the search-service owner and a backup. Give them a recurring queue for failed searches, broken connectors, access changes and expired content. Expand one source or team at a time and rerun the restricted-identity checks. For new-hire questions, continue with the knowledge-assistant onboarding guide.
What practitioner reports add
In a workplace-search evaluation thread, u/sibraan_ described strong known-file retrieval but difficulty synthesizing their organization's cross-system decisions, and a Guru maintenance burden their team did not sustain. Another participant, u/PomeloThomas2665, favored Glean's relevance on their Notion, Slack and Drive corpus. These are anonymous, unverified reports with different environments, not controlled comparisons or current product guarantees. They justify testing retrieval, synthesis and ownership separately; they do not establish a winner.
We reviewed public documentation, pricing and attributed discussion. We did not connect a private tenant, run the proposed pilot, measure accuracy or verify an invoice. The usable output of this guide is a buyer-run evaluation plan with explicit failure conditions.
Sources & further reading
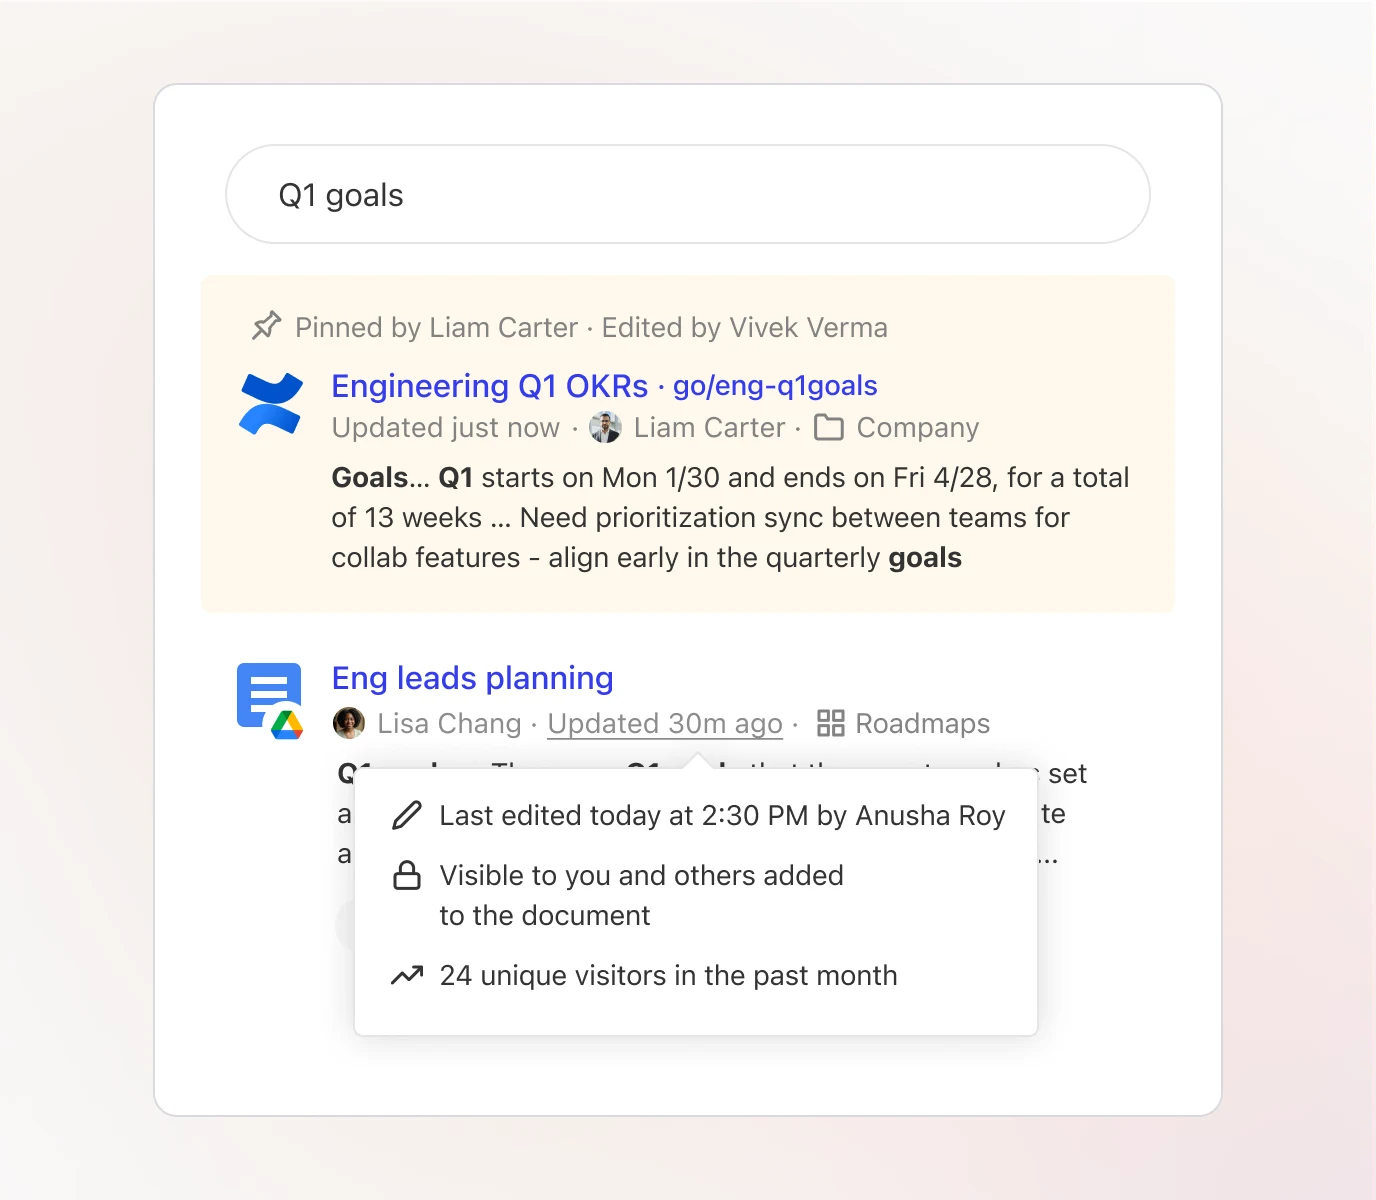
- Glean enterprise search and interface illustration
- Glean connector architecture
- Glean crawl and deletion behavior
- Glean Salesforce field-access boundary
- Glean Core Suite pricing
- Glean Enterprise Flex pricing
- Guru pricing
- Guru source access and sync limits
- Slite pricing and allowances
- Slite pooled questions and credits
- Slite Agent source access modes
- Attributed workplace-search evaluation discussion


Ordered for comparison, not as a universal ranking. Inclusion requires a direct fit with this page's stated workflow.